RoboCasa365Leaderboard

Benchmarking generalist robot policies on the multi-task learning benchmark

50 Tasks
13 Models Evaluated
3 Evaluation Splits
Updated 09/12/2026

Leaderboard

Rank Model Submitter Overall Atomic-Seen Composite-Seen Composite-Unseen Open Source
🥇 Xiaomi Robotics 57.4 80.2% 57.1% 32.1% ✓
🥈 AMAP CV Lab 46.6 79.4% 48.3% 7.9%
🥉 AMAP CV Lab 40.3 75.6% 37.7% 3.3%
#4 TeleAI 39.6 66.3% 30.3% 18.8% ✓
#5 RLWRLD 36.0 67.6% 27.9% 8.5% ✓
#6 World Agents 35.3 66.3% 26.7% 9.0% ✓
#7 RoboCasa Team 23.9 50.7% 14.8% 2.7% ✓
#8 RoboCasa Team 21.9 51.1% 9.4% 1.7% ✓
#9 GigaAI 20.7 44.4% 11.8% 2.9% ✓
#10 RoboCasa Team 16.9 39.6% 7.1% 1.2% ✓
#11 RoboCasa Team 14.8 34.6% 6.1% 1.1% ✓
#12 GitHub: yuxin101 12.6 30.3% 3.8% 1.6%
#13 RoboCasa Team 6.1 15.7% 0.2% 1.3% ✓

Note: For fairness and consistency, GR00T N1.5 was re-evaluated with a 1.5x longer horizon relative to the paper’s reported results and reflects the RoboCasa 1.0.1 update

Click a policy name to open its submission details (codebase, checkpoint, training configuration, and additional information)

1 Benchmark scope

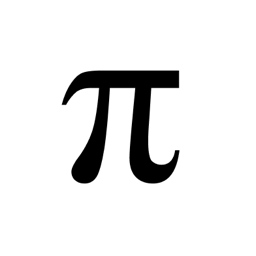
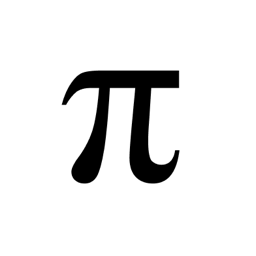
RoboCasa365 is a large-scale benchmark for generalist robot policies spanning 365 everyday tasks across 2,500 diverse kitchen environments. This leaderboard focuses on the multi-task learning setting and includes the four baseline policy families: Diffusion Policy, π0, π0.5, and GR00T N1.5.

The current leaderboard highlights the first public comparison and will continue to grow as users submit additional models. New entries are added after submission review and verification so results remain consistent and trustworthy. Results are reported on a 50-task multi-task benchmark spanning atomic manipulation and longer-horizon composite kitchen skills.

2 How we evaluate

For this first release, the Overall score is the published average task success rate on the 50-task multi-task benchmark. It aggregates three evaluation splits: Atomic-Seen (18 tasks), Composite-Seen (16 tasks), and Composite-Unseen (16 tasks). For more details, see our benchmarking documentation.

Policies are trained on the Human300 pretraining dataset (300 tasks across 2,500 pretraining kitchens) and evaluated on the 50 target tasks in pretraining kitchens. Atomic-Seen and Composite-Seen tasks appear in pretraining, while Composite-Unseen tasks are held out from pretraining and evaluated zero-shot for generalization to novel composite tasks.